

There Is No Best AI Model for Everything
No best AI model exists for every task: each model excels at a group of tasks, and the true cost of a model should be calculated per completed task, not per token price. The right way to choose is to identify your work, test 2–3 models on your own data, then compare the cost for each usable result. This article explains how to read benchmark rankings correctly, a table of suggestions by task group, and a process to test quickly in one afternoon. According to the summary "The 2026 AI Model Showdown" by @kinderlayer (13/10/2026), the same model like Opus 5.5 or Haiku 5.5 can cost $0.07 or $0.61 per attempt depending on effort level. That example shows why you must measure on real work. First identify your task, next test a few models, finally calculate the cost for each usable result.
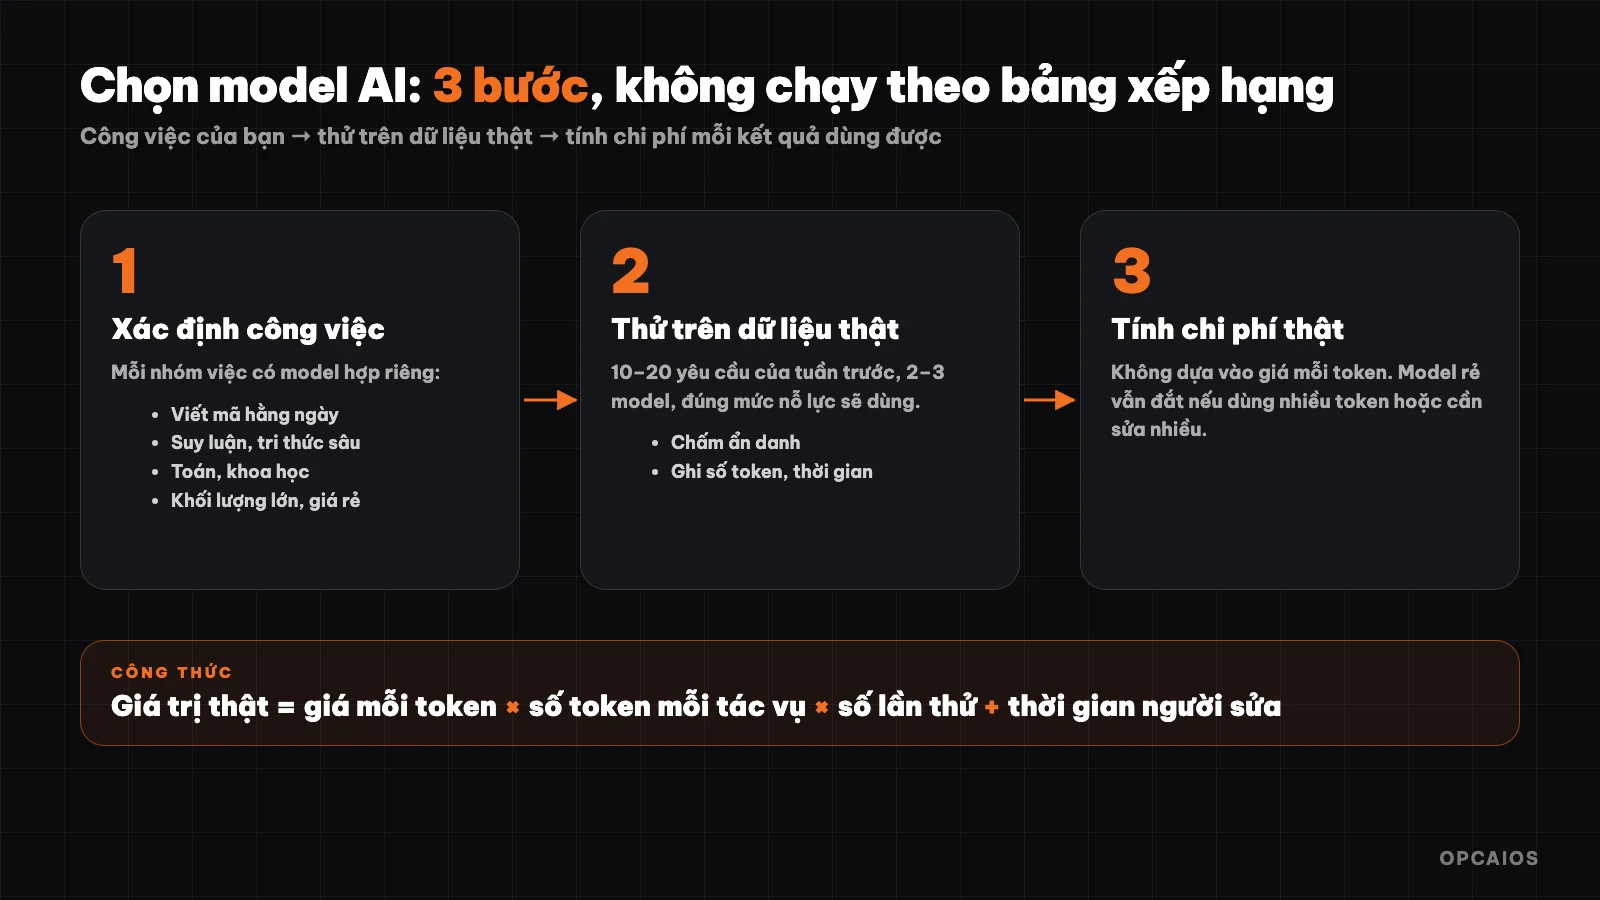
Three steps to choose an AI model instead of following the rankings. Diagram: OPCAIOS.
Why Does No Best AI Model Exist for Every Task?
No best AI model exists for every task because each company optimizes for a different set of test questions, and those tests measure different abilities: writing code, scientific reasoning, working with software on screen, or handling large volume at low cost. A model ranking first on one table usually ranks in the middle on another.
According to the summary by @kinderlayer (13/10/2026), in the code-writing group, the three top models differ by just a few percentage points and rankings shift depending on who runs the test and at what effort level. In the reasoning and professional knowledge work group, one model leads clearly; in the math and science group, another leads. This data is compiled from many sources, and OPCAIOS has not independently verified it, but the principle holds true at any time: an article claiming one model is "far ahead of everything else" usually rests on one video, one test, or one lucky run.
So the question should shift from "which model is strongest?" to "which model fits this work best, at a price I can afford?".
How Do I Read AI Model Benchmark Rankings Correctly?
A benchmark is a standardized test used to compare abilities between models, and the score for the same model can vary widely depending on how it is run. According to @kinderlayer's summary (13/10/2026), three factors change the score but are rarely explained clearly in the rankings.
- Effort level. Most published scores are at maximum effort. For example, Haiku 5.5 achieves 72.4% on the OSWorld computer-use test at maximum effort but only 42.0% at low effort, while the cost per attempt rises from $0.07 to $0.61.
- Scoring method. That 72.4% figure is a subset run offline with partial scoring; the strict pass rate is only 37.1%.
- Who runs the test. An analysis by Vellum, quoted in an article, recorded the same Claude model varying by up to 5.4 points between different testing parties.
Scores published on launch day are usually the tables from the maker themselves, run under conditions they chose. Treat every number as a trend, not a conclusion. The only decisive test is your own workload.
How Does Cost Per Task Differ from Cost Per Token?
Cost per task is the total real money for a model to finish one job, equal to the price per token multiplied by the number of tokens the model uses for that job. A model with a cheap per-token price can still be more expensive if the model "thinks" using more tokens.
An example from @kinderlayer citing Artificial Analysis: Opus 5.5 has a lower per-token price than GPT-6 Astra, but at maximum effort Opus writes about 119 thousand tokens per task compared to about 27 thousand for Astra. The result is that each task costs Opus about $5.98 versus $3.26 for Astra, and running the full set costs about $8,708 versus $5,324. When Opus is lowered to medium effort level, the gap narrows sharply, meaning the effort level dial is also part of the price.
A lesson to apply right now: before comparing price tables, measure the tokens a model uses on real work. Most providers, including OpenAI and Anthropic, return the number of tokens used in each API response, enough to calculate the cost for each run.
Which Job Groups Work Best with Which Model Types?
The table below suggests how to match job groups with model types, based on @kinderlayer's synthesis from October 2026. The figures change quickly, so think of this as a starting point to experiment with, not a final conclusion.
| Job Group | Selection Direction | Main Reason |
|---|---|---|
| Daily coding | Mid-tier or high-tier models, roughly equal | Quality differences fall within the margin of error, price differences are large |
| Reasoning, deep specialist knowledge work | Leading reasoning models | The largest score gap is in this group |
| Math, science, abstract problems | Science-strong models | Cheaper models fall behind clearly in this group |
| Filtering, classification, extraction, bulk draft writing tasks | Small, cheap models | Most real-world work doesn't need leading models |
| Software automation agents | Try both, compare cost per task | Quality is roughly equal, cost difference varies |
General principle: use small models for 90% of simple work, step up to mid-tier models when work gets harder, and only call leading models for decisions that need judgment. Popular assistants like ChatGPT, Claude, and Gemini all have multiple model tiers, so you can still choose by price from the same provider.
How Can I Test Models on My Own Work in One Afternoon?
Testing models on real work means running the same set of requests through 2–3 models, comparing results and costs, instead of trusting someone else's ranking. The five-step process below requires no coding knowledge, and with a batch of 10 requests you usually finish in a few hours.
- Pick 10–20 real requests from last week's work, mixing easy and hard ones—for example, draft articles for clients, reply emails, tables that need summarizing.
- Run the same batch through 2–3 models, say OpenAI's ChatGPT, Anthropic's Claude, and Google's Gemini, at the effort level you'll actually use.
- Score blind: shuffle the model names, then rate each result on a simple scale (usable right away, needs light fixes, needs rebuilding).
- Record token count and time for each run, then calculate the cost for each usable result.
- Add human fixing time: a cheap model that needs heavy editing might cost more than an expensive model you can use right away.
Quick formula: real value = cost per token × tokens per task × number of tries + human fixing time. To check independent data and pick a candidate, see What is Artificial Analysis.
When Should I Use Multiple Models Instead of One?
Using multiple models is a way to divide work by difficulty: cheap models do most of it, expensive models only show up where judgment is needed. This approach also cuts risk from depending on one provider, since prices and policies can change anytime in 2026 and beyond.
A common tiered structure in automation workflows has three layers:
- First layer uses small models to filter, classify, and extract.
- Middle layer uses mid-tier models to draft and handle medium-hard work.
- Final layer uses leading models for review or decision-making.
For example, by @kinderlayer's figures from Artificial Analysis, one task costs around $5.98 on one model and $3.26 on another, so running it thousands of times will make the gap significant. If you build a workflow with n8n or Claude Code, swapping the model at each step is just changing one parameter. Set a common test suite for the output, since each model has different habits, and retry when the provider releases a new version.
Frequently Asked Questions
What is the strongest AI model right now?
There is no strongest model for everything. According to @kinderlayer's summary, each group of tasks has its own leading model: deep reasoning, math and science, everyday coding, or handling large volumes cheaply. Choose based on your group of tasks.
Does a more expensive model always give better results?
No. For many simple tasks like classification or extraction, smaller models give results nearly equivalent to much cheaper prices. Expensive models are worth their cost for work that needs deep reasoning or judgment.
Which benchmark ranking should I rely on?
Use an independent ranking to pick candidates, then test yourself on real work. Scores in rankings change based on effort level, scoring method, and who runs the test, so don't use them to replace your own testing.
How do I calculate the real cost when using an AI model's API?
The real cost when using an API is the total money to get one usable result, including token price, number of tries, and time spent by the person fixing it. First, multiply the price per token by the number of tokens the model uses for each task; this number usually comes in the response from OpenAI, Anthropic, or Google's API. Next, multiply by the number of tries. Finally, add the time the person spends fixing the result. For example, according to @kinderlayer's post, one task costs about $5.98 on one model and about $3.26 on another model even though the more expensive model has a lower price per token, because the number of tokens used differs. See the post What is an API if you're not familiar.
How often should I test again when there's a new model?
You should test again each time your provider releases a new version or changes prices, or about every quarter if there's no change. The reason is that the October 2026 ranking may differ from the next month, and a comparison from three months ago is testing a different model from the one you use today. Keep 10–20 sample requests and the scoring sheet from last time, for example in a spreadsheet, then retesting takes only a few hours. To build an AI application process for a small team, see AI application training course.
Source: data and model names from @kinderlayer's summary post "The 2026 AI Model Showdown" on X (13/10/2026), citing Artificial Analysis, Vellum and others; OPCAIOS has not independently verified. The testing steps are OPCAIOS's guidance.
Translated from Vietnamese with AI. Read the original.
Want to apply this in your business?
Book a free 30-minute call (Vietnam time, in English or Vietnamese).