

What is RAG?
RAG (Retrieval-Augmented Generation) is a method that retrieves relevant information from a knowledge base and adds it to the prompt sent to an AI model, so the answer is based on your actual data instead of just relying on the model's memory. The concept was introduced by Patrick Lewis and colleagues in a paper published on May 22, 2020 (accepted at NeurIPS 2020). This post explains what RAG is, how it works, when you don't need RAG, why retrieval often fails and how to fix it according to Anthropic's data, how to choose a vector database and embedding model for Vietnamese, and OPCAIOS's real experience building semantic search with pgvector.
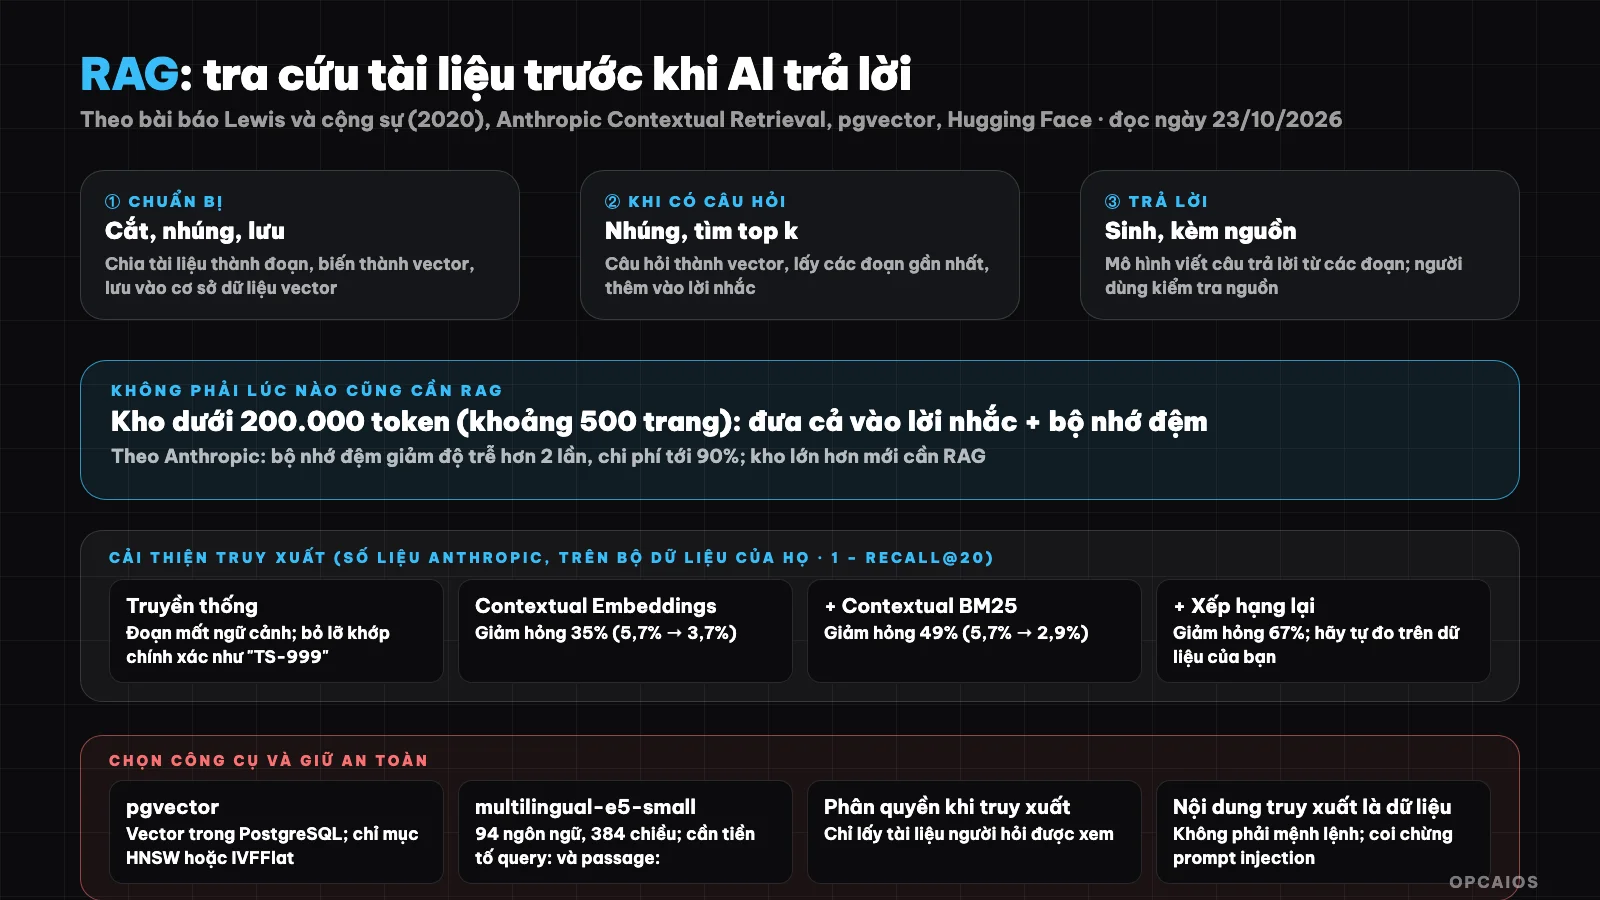
RAG has two halves: preparing the knowledge base (chunking, embedding, storing) and answering (embedding the question, retrieving, generating). Diagram: OPCAIOS.
What is RAG and why was it created?
RAG is a method combining two types of memory: memory in the model's parameters and external memory that can be looked up. The original paper by Patrick Lewis and colleagues (arXiv:2005.11401, published May 22, 2020) identifies three problems with large language models, according to the abstract (read October 23, 2026):
- The ability to access and manipulate knowledge accurately within parameters is limited.
- The issue of citing sources for decisions remains unresolved.
- The issue of updating knowledge also remains unresolved.
The authors proposed a pretrained generative model paired with a dense vector index of Wikipedia. The model accesses the index through a neural retriever. They report best results on three open-domain question-answering tasks (NeurIPS 2020). Additionally, on language generation tasks, the RAG model produces more specific, diverse, and factually correct language than a parameter-only model. Simply put, it's like an open-book exam: instead of making the model memorize everything, you let the model find the right page of the document before answering.
What steps does RAG go through?
RAG is a process with two parts: preparing the knowledge base and answering when a question comes in. According to Anthropic's guidance (read October 23, 2026), the steps are as follows:
Preparation (done once, updated when documents change):
- Split the document repository into small chunks, usually no more than a few hundred tokens.
- Use an embedding model to convert each chunk into a vector encoding its meaning.
- Store the vectors in a database that allows semantic similarity search.
When a question arrives:
4. Embed the question into a vector.
5. Find the nearest chunks to the question (top k).
6. Add those chunks to the prompt sent to the generative model.
7. The model answers based on those chunks, ideally with sources so users can verify.
For example, OPCAIOS uses pgvector in PostgreSQL as its vector database.
| Component | Role | Example |
|---|---|---|
| Chunker | Divide documents into retrieval units | By heading, paragraph, few hundred tokens |
| Embedding model | Convert text to vectors | multilingual-e5-small (384 dimensions) |
| Vector database | Find nearest chunks | pgvector in PostgreSQL |
| Reranker (optional) | Re-filter top chunks by relevance | Reranker model |
| Generative model | Write answers from chunks | Claude, GPT, Gemini |
When do you not need RAG?
You don't need RAG when your knowledge base is small enough to fit entirely in a prompt. Anthropic says if your base is under 200,000 tokens (about 500 pages), you can fit the whole base in the prompt without needing RAG. With prompt caching, according to Anthropic, latency drops by more than 2x and costs drop up to 90% (read October 23, 2026). When your base is larger than the context window, RAG is a common solution. Example scenario: a small business with 40 pages of internal procedures should try putting the entire document set in the prompt first, then consider RAG. Also, choose simplicity first, because many small businesses have a document set small enough to start without RAG. For cost based on usage level, see Which AI model should you choose?.
Why does RAG retrieve incorrectly, and how do I fix it?
RAG retrieval errors occur when the retrieval step doesn't provide the model with the correct relevant passages. There are two main causes, according to Anthropic (read on 23/10/2026) and the "Contextual Retrieval" paper (Anthropic 2024). First, traditional RAG loses context when chunking: a passage like "revenue increased 3% compared to last quarter" doesn't say which company or which quarter, so it gets retrieved incorrectly. Second, embedding models are good at capturing meaning but may miss exact matches: for the question "Error code TS-999" the model might find general error code content but miss the exact "TS-999". Three ways to fix this:
- Combine BM25 with vector search: BM25 is a ranking function based on term matching, effective for identifiers and technical terms.
- Contextual Retrieval: add a short context passage written by a model to the beginning of each passage before embedding.
- Reranking: get many candidates then filter them again, both better and reduces cost and latency.
What do Anthropic's test results show?
According to Anthropic's data (the "Contextual Retrieval" paper, 19/9/2024), measured by retrieval failure rate, which is the rate that relevant passages don't appear in the top 20: Contextual Embeddings reduced it by 35%, from 5.7% to 3.7%. Combining Contextual Embeddings and Contextual BM25 reduced it by 49%, from 5.7% to 2.9%. Adding reranking reduced it by 67%. Anthropic estimates the cost of creating context one time at about $1.02 per million document tokens when using prompt caching. These are results on their datasets (source code, novels, scientific papers), so measure again on your own data; Anthropic itself also recommends always running evaluation on your own case.
How do I choose a vector database?
If you already use PostgreSQL, pgvector is the simplest choice for a vector database. It's an open source extension that adds vector search to Postgres, according to pgvector's README (read on 23/10/2026). The extension stores vectors alongside other data and supports both exact and approximate search. Distance types include L2, dot product, cosine, L1, Hamming and Jaccard. You also keep Postgres benefits like ACID, point-in-time recovery and JOIN. There are two types of approximate indexes:
- HNSW: creates a multi-layer graph, with better speed and accuracy but slower index building and higher memory usage. This type doesn't need existing data to build the index.
- IVFFlat: builds faster, but needs data before creating the index.
Approximate indexes trade off some accuracy for speed, so results may differ when adding an index. For example, if you already use Supabase then that's PostgreSQL ready to go; see What is Supabase?.
Which embedding model for Vietnamese?
An embedding model for Vietnamese should be multilingual, and you need to verify it with your own data. One example is multilingual-e5-small from the intfloat organization on Hugging Face, with a technical report by Liang Wang and colleagues. According to the model card on Hugging Face (read on 23/10/2026), the model has 12 layers, embedding size 384, supports 94 languages and uses the MIT license. There's one technical detail that's easy to get wrong: the model card requires each input text to start with "query: " or "passage: ", even for non-English text. Specifically, use "query: " for questions and "passage: " for document passages. If you forget the prefix, retrieval quality drops but the system doesn't report an error. OPCAIOS uses this very model for internal semantic search, as described in the experience section below.
How do I evaluate a RAG system?
Split evaluation into two parts: does retrieval get the right passages, and is the answer correct and sourced. Practical way to do it:
- Create a set of 30 to 100 real questions each with the correct document passages.
- Measure whether the correct passages appear in the top k (recall@k, as Anthropic uses with k = 20).
- Manually read a sample of answers: are they hallucinating, are sources cited correctly.
- Repeat each time you change chunking, embedding model or prompt.
Risks and Security Considerations When Using RAG
The risk of RAG is that the model can still give wrong answers or leak data, because RAG reduces rather than eliminates errors. Five points to keep in mind before deploying RAG to real users:
- Permissions at the retrieval step: only retrieve documents the user is allowed to see; if you put internal documents in a shared repository, someone without permission could see them through the answer.
- Retrieved content is data, not instructions: a document can contain sentences designed to manipulate the model (prompt injection); see the principles in What is MCP?.
- Personal data: consider whether to put customer data in the repository and in the prompt sent to the model provider.
- Outdated documents: the repository must be updated; old sections will give old answers.
- Show sources: always show users the document excerpt used so they can verify it.
OPCAIOS's experience: semantic search with pgvector
OPCAIOS built the retrieval part of RAG for an internal admin area: semantic search across projects, tasks, discussions, support tickets, documentation, customers, customer exchanges, and sales opportunities. A table stores excerpts with a 384-dimensional vector column in PostgreSQL with pgvector, using HNSW indexing with cosine distance; text is embedded using the multilingual-e5-small model running in a separate service that only listens internally, with "query: " and "passage: " prefixes; content is hashed so it only re-embeds when a record changes, and each indexing run has a limit on the number of excerpts. If the embedding service is not configured, the admin area falls back to keyword search. Only internal admin data is indexed. This is half of "retrieval" (R): we use it to find the right records, we haven't built a chatbot that writes answers from those excerpts, and we haven't published accuracy numbers. At the memory layer of the AIOS system, large documents and knowledge are also stored in a vector database with document, excerpt, and vector structure, for agents to query.
How to start building RAG?
- Define questions and documents: choose a group of documents and 30 real questions.
- Try without RAG first: if documents are small, put them in the prompt with context windows.
- Cut excerpts by meaning: by headings and paragraphs, a few hundred tokens, with source title attached.
- Choose a multilingual embedding model and an available vector database (like pgvector).
- Add keyword search and re-ranking if measurement shows retrieval is missing results.
- Show sources, set permissions, measure before giving real users access. To automate repository updates, see n8n or Make.
Read more: How to Build an AI Chatbot That Self-Learns Internal Documents (RAG) Using Dify and Supabase, 5 Best Memory Tools for AI Agents in 2026.
Frequently Asked Questions
What is RAG?
It's a method to retrieve relevant information from a knowledge base and feed it into a prompt so an AI model can answer based on real data, usually with sources. The concept comes from a paper by Lewis and colleagues in 2020.
How is RAG different from fine-tuning?
RAG brings knowledge in at query time through retrieval and can be updated by changing documents, while fine-tuning modifies the model's parameters. RAG works well with changing knowledge and when you need to cite sources.
Do I need RAG if I have little documentation?
Not necessarily. Anthropic says if your knowledge base is under 200,000 tokens (around 500 pages), you can put everything into the prompt and use prompt caching to be faster and cheaper.
Why does RAG give wrong answers even with documents?
RAG gives wrong answers despite having documents usually because retrieval is broken, meaning the search step doesn't bring the right passages to the model. There are three common reasons. First, passages lose context when cut, for example a passage that just says "revenue increased 3%" without saying which company. Second, embedding models miss exact matches like error codes or proper names. Third, the correct passage doesn't land in the top k. Combining BM25, Contextual Retrieval, and reranking helps reduce these errors: according to Anthropic, broken retrieval drops 49% with Contextual Embeddings plus Contextual BM25 and drops 67% when you add reranking, on their datasets (read 23/10/2026). Measure this again on your own data before trusting these numbers.
What should I watch out for when doing RAG in Vietnamese?
Use multilingual embedding models, test with real questions, and follow the prefix requirements of your model (like "query: " and "passage: " with E5). Want to learn how to build AI systems with your own data, check out OPCAIOS's AI application training course.
Sources: paper "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks" (arXiv:2005.11401, NeurIPS 2020); Anthropic's "Contextual Retrieval" post (19/9/2024); pgvector README; intfloat/multilingual-e5-small model card on Hugging Face; direct reading on 23/10/2026. Anthropic's numbers are on their test datasets. Implementation experience is from OPCAIOS, without accuracy numbers attached.
Translated from Vietnamese with AI. Read the original.
Want to apply this in your business?
Book a free 30-minute call (Vietnam time, in English or Vietnamese).